
Feature
Chat models that make images, video and audio
In ClawAI a chat model such as Grok, GPT or Gemini can generate images, video and audio through tools, wait for the result and then write its answer about it.
All features · Last reviewed:
See it in the app
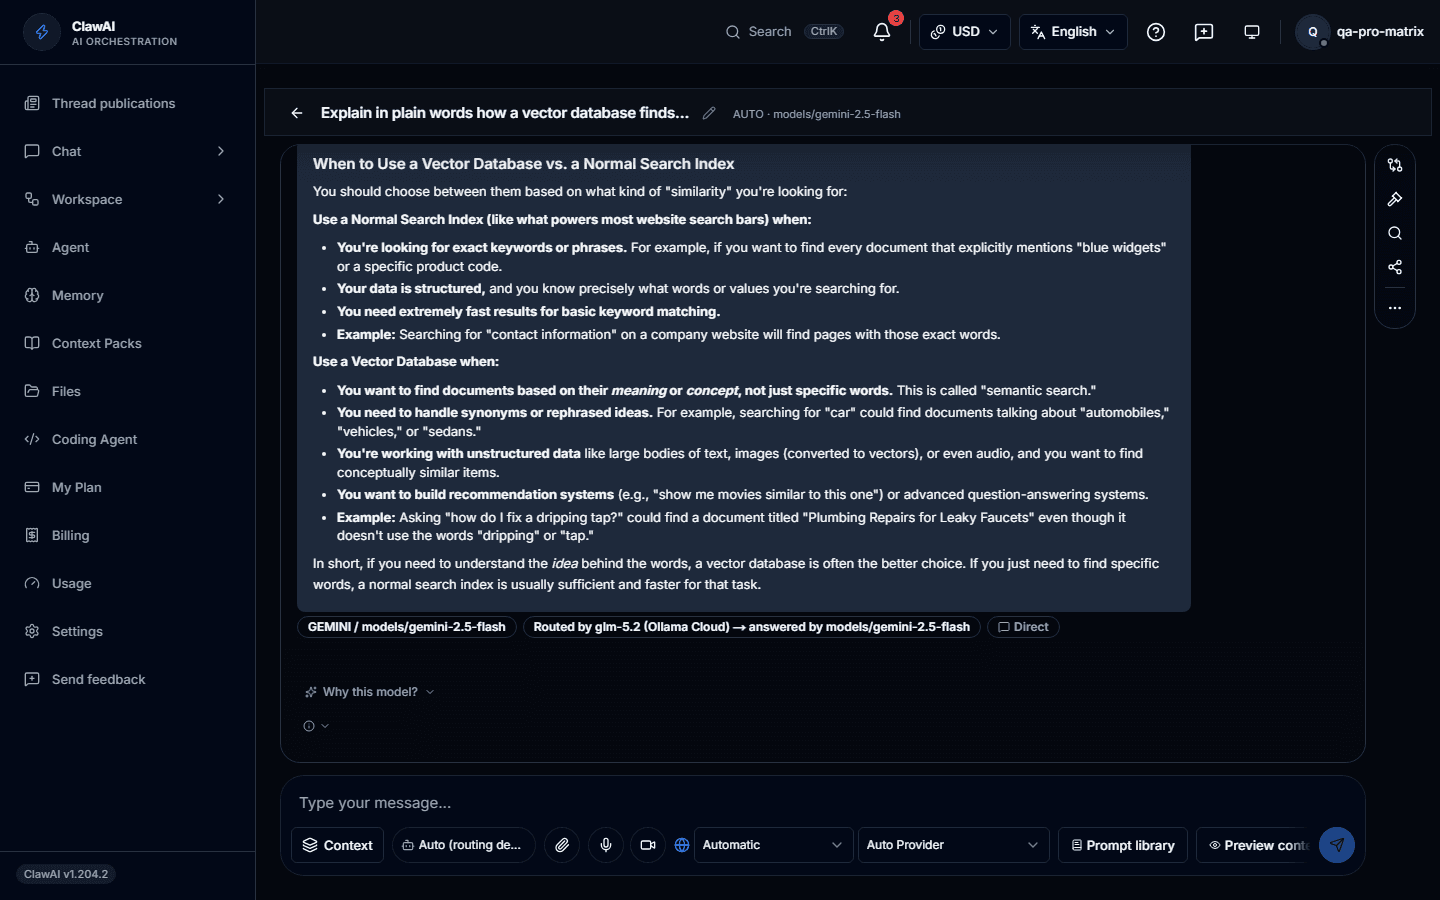
Every answer shows which model wrote it and why. 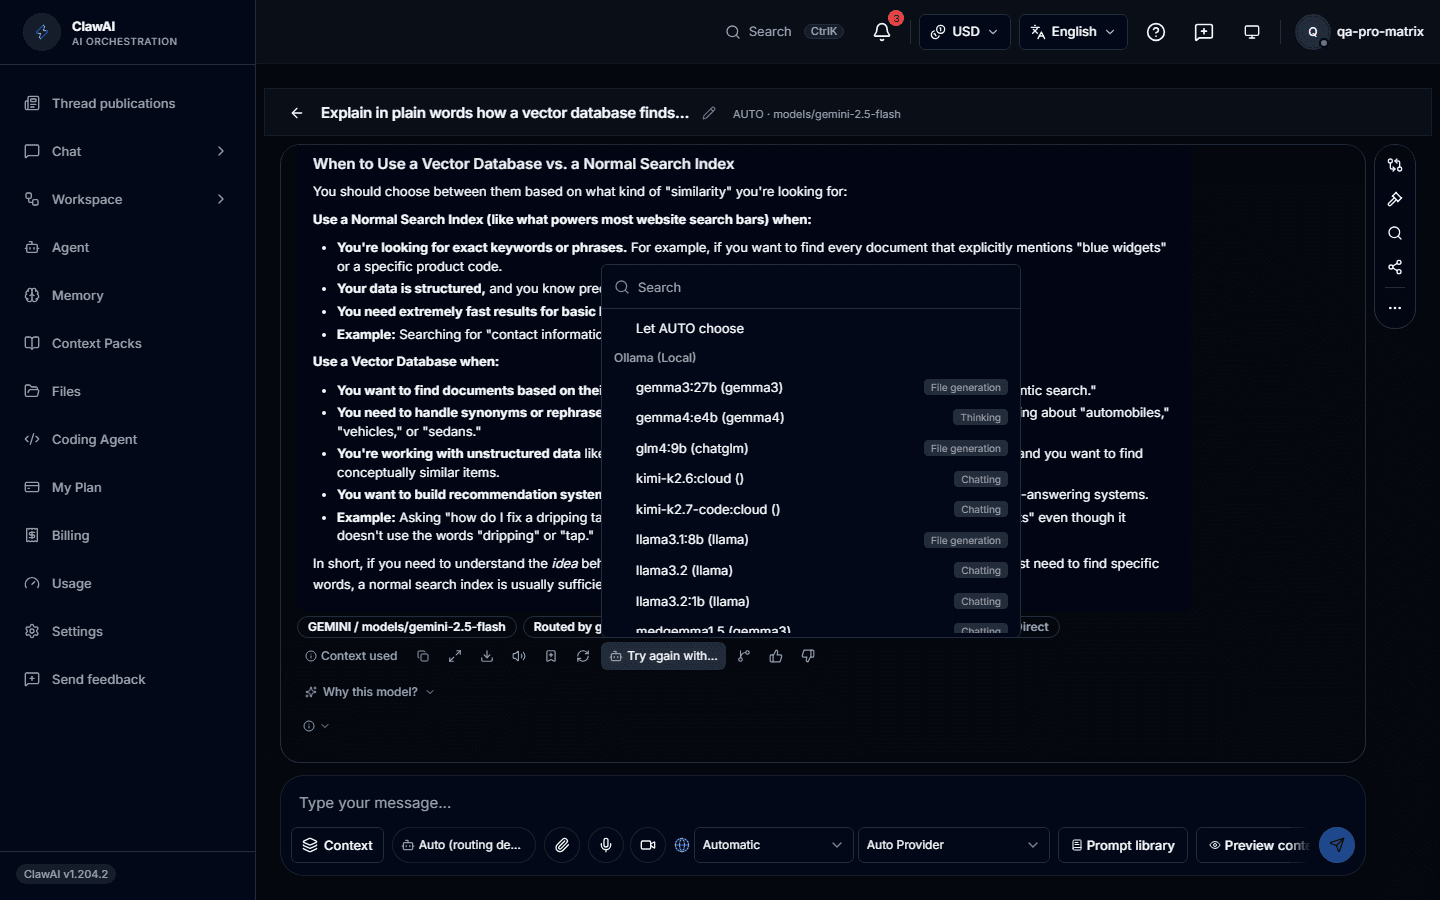
Pick a model yourself, or let AUTO choose.
The model asks, ClawAI makes, the model answers
When your message calls for media, the chat model can call one of three tools: generate image, generate video or generate audio. ClawAI runs the media model, waits for it to finish and gives the result back to that same chat model, so the reply you read was written by the model that saw what was made. The finished image, video or audio appears under the answer. Models that cannot call tools keep the older shortcut, where a separate media model answers the request.
Works with Grok, GPT and Gemini
Any chat model that supports tool calling can use the tools, including Grok, GPT and Gemini models. A model that does not generate media itself, Claude among them, can still ask for it, because the media is made by dedicated image, video and audio models behind the tools and not by the chat model.
Images, video and audio
Images come from Gemini, OpenAI or xAI image models, video from Veo or Grok Imagine, and audio as speech (OpenAI or Gemini voices) or short pieces of music (Gemini Lyria). Which models are available depends on what the operator has connected. A chat model may name a model, but only one on the platform's known list; anything else falls back to the default.
Waiting, limits and cost
Generation is metered like any other generation: it draws on your plan allowance or your pay-as-you-go credit, and it is refused when neither covers it. A turn that makes media is not streamed word by word, because the model has to wait for the result. One answer can make up to two items, and one message up to three across a Compare view, each with a bounded wait.
Questions people ask
- Which chat models can make media?
- Any chat model that supports tool calling, for example Grok, GPT and Gemini models. The media itself is produced by image, video and audio models behind the tools, so a model that cannot generate media on its own, such as Claude, can still ask for it.
- Where does this work?
- In normal chat and in Compare lanes. The other orchestration labs (consensus, escalation, best-of-N and so on) do not offer the media tools yet; they keep the older behaviour, where a request for an image goes to an image model.
- What does it cost?
- Each generation is metered from your plan allowance or your pay-as-you-go credit, on top of the chat model's own tokens. The pricing page shows what each plan includes.
Try it rather than take our word for it
Chat models call generate_image, generate_video and generate_audio; the image service makes the media and the same chat model writes the reply, metered like any other generation.