
Use case
Comparing model answers with ClawAI
How ClawAI’s Compare and Judge modes run one prompt across several models side by side and have a judge model assess the results — grounded in the shipped feature, no invented rankings.
All use cases · Last reviewed:
See it in the app
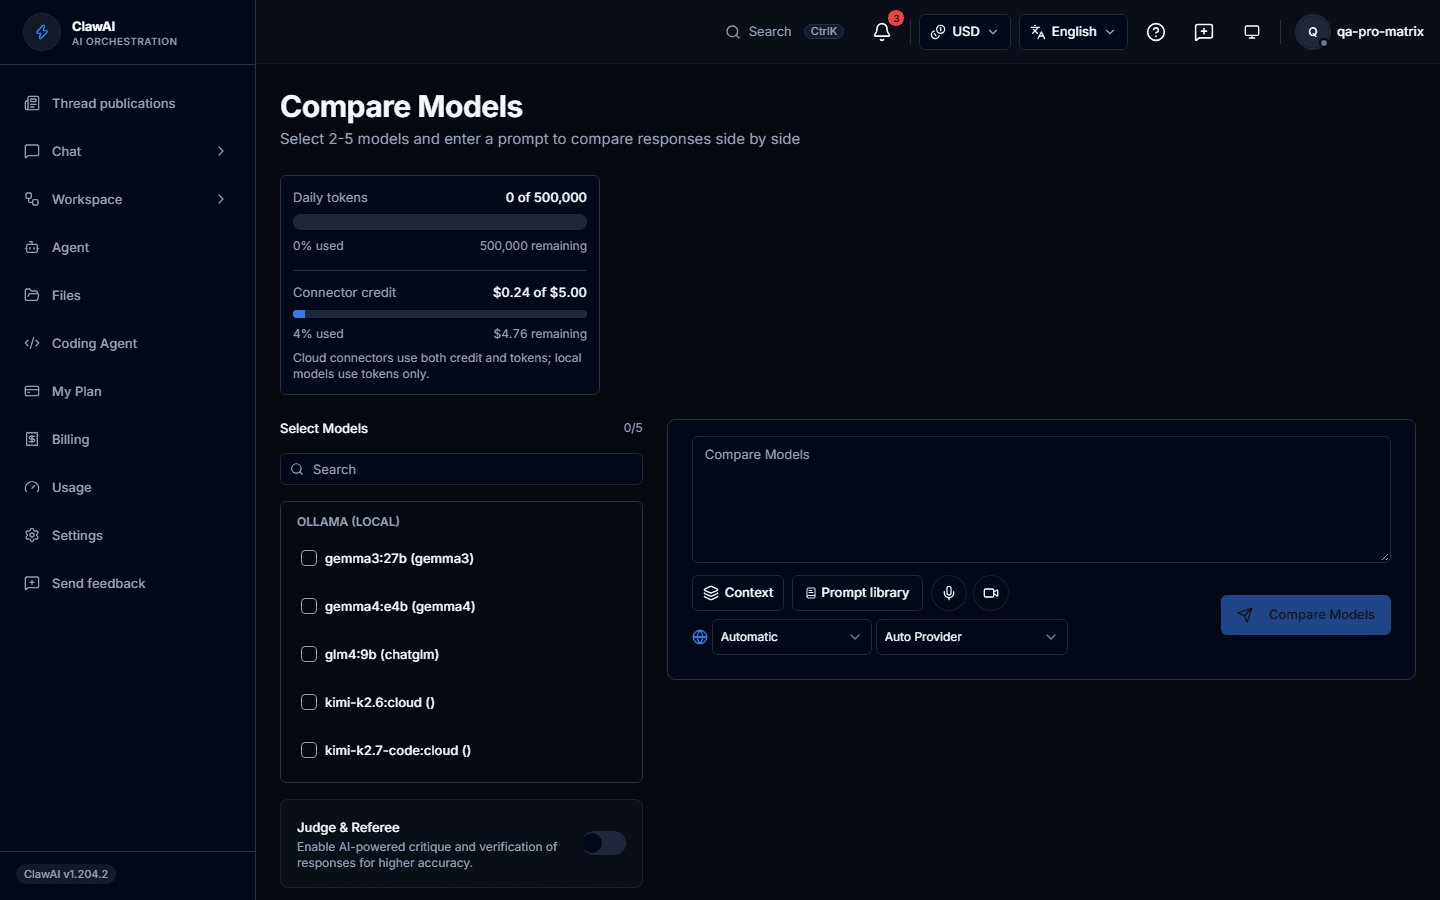
Ask one question and see three models answer side by side. 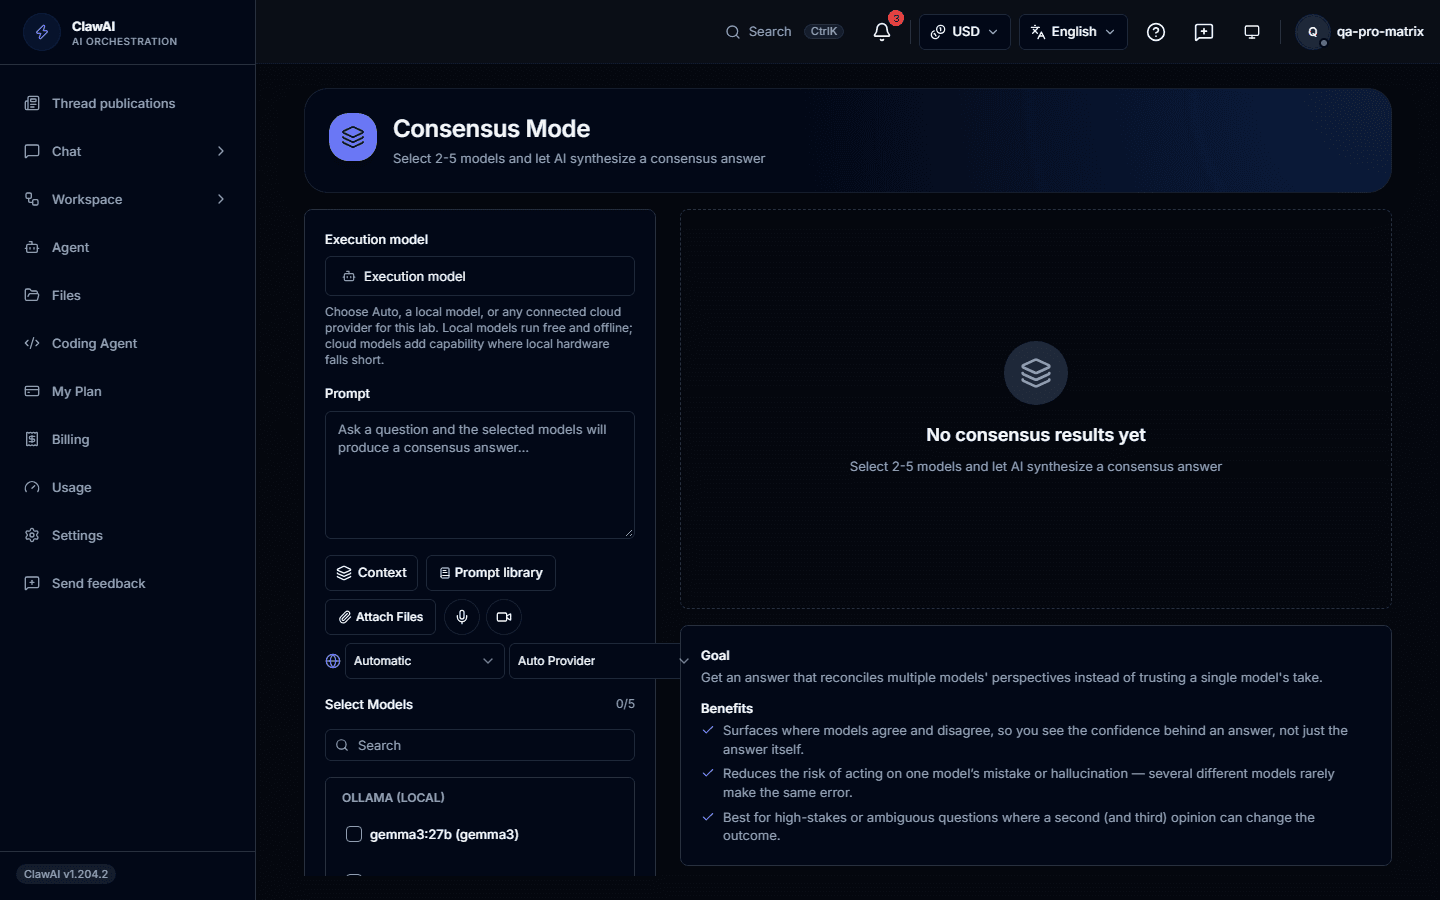
Let several models answer, then reach one agreed answer.
What Compare mode does
Compare mode sends one prompt to several models at once and shows the responses side by side, so a decision that matters — a judgment call, an ambiguous request, a case where one model’s framing might be wrong — gets more than one perspective. It is a plan-gated feature, metered per lane rather than per run, so cost scales with how many models you compare.
Consensus and best-of-N, explained properly
Two ideas describe what you do with several answers once you have them: consensus, where agreement across models is itself informative, and best-of-N, where you generate several candidates and pick or synthesize the strongest. See what is AI consensus and what is best-of-N, both linked below, for how each actually works rather than a marketing gloss.
Having a model judge the rest
Judge mode is a separate plan-gated feature that runs a second pass over a Compare run, with one model assessing the others rather than you reading every response by hand. Critic review is a related, separate feature for a second look at a single answer rather than a comparison across models — see what is an AI judge, linked below, for how the assessment actually works.
Questions people ask
- What is the difference between Compare mode and Judge mode?
- Compare mode runs one prompt across several models and shows every response side by side. Judge mode is a separate, plan-gated second pass that has a model assess the results of a Compare run instead of you reading each one.
- Does Compare mode cost more than an ordinary chat message?
- Compare usage is metered per lane, not per run — running the same prompt against more models costs proportionately more. Confirm the current allowance on the pricing page.
- What is best-of-N, and is it the same as consensus?
- No — consensus treats agreement across model answers as informative in itself, while best-of-N generates several candidates and picks or synthesizes the strongest. See what is AI consensus and what is best-of-N, both linked below.
Try it rather than take our word for it
ClawAI’s Compare and Judge modes are real, shipped, plan-gated features — one prompt across several models, with an optional second model to assess the results.